DeepFinance: Can AI Diligence a $100MM Deal? (arXiv (Cornell University))
SaveSummary
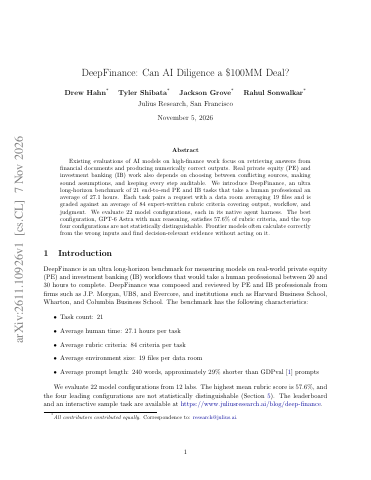
- DeepFinance introduces an ultra long-horizon benchmark consisting of 21 end-to-end private equity and investment banking tasks that take a human professional an average of 27.1 hours to complete.p.1
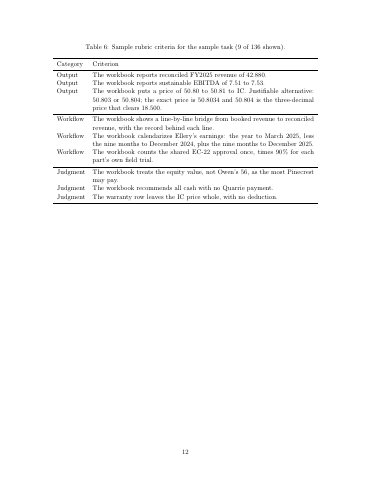
- Each benchmark task pairs an assignment request with a data room averaging 19 files and is evaluated against an average of 84 expert-written rubric criteria covering output, workflow, and judgment.p.1
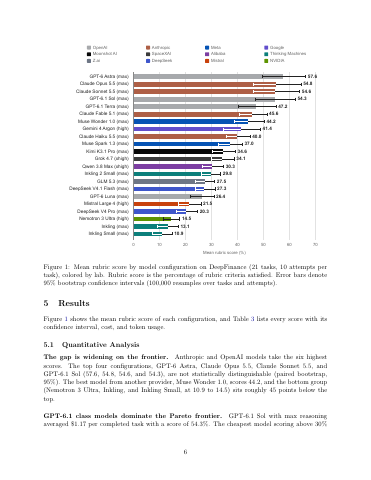
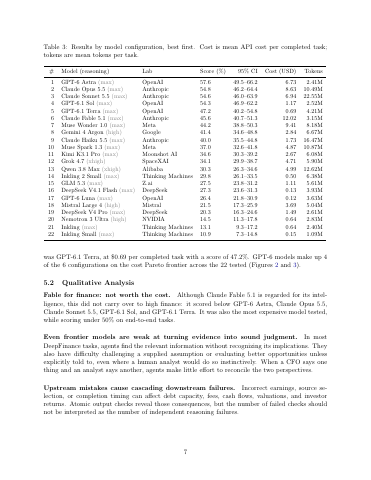
- Evaluation of 22 model configurations across 12 labs shows the top model configuration, GPT-6 Astra with max reasoning, achieves a leading mean rubric score of 57.6%.p.1
- The four highest-scoring configurations (GPT-6 Astra, Claude Opus 5.5, Claude Sonnet 5.5, and GPT-6.1 Sol) are statistically indistinguishable, ranging between 54.3% and 57.6%.p.6
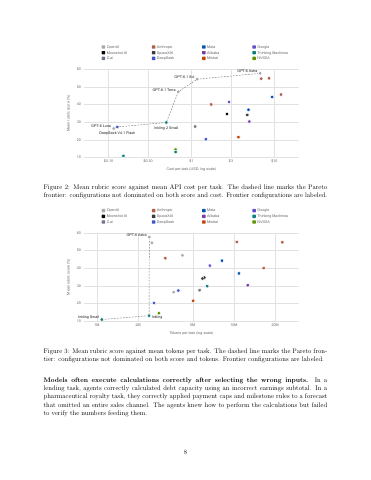
- GPT-6.1 Sol with max reasoning achieved a 54.3% rubric score at an average API cost of $1.17 per completed task, placing it on the cost Pareto frontier.p.6
- Frontier models frequently perform calculations accurately from incorrect inputs and locate decision-relevant evidence without acting upon it in their decisions.p.1
Key insights
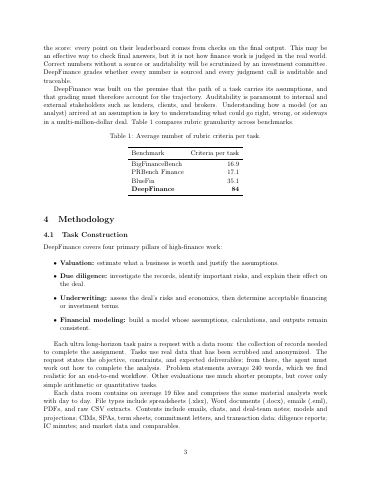
- Traditional finance benchmarks overemphasize simple question-answering over documents, whereas DeepFinance grades end-to-end workflows against up to 140 criteria.p.2
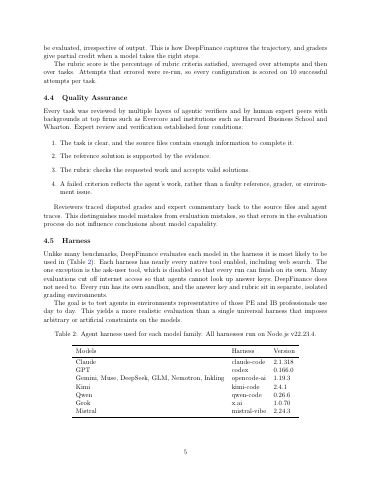
- Evaluations grade models in their native agent harnesses with full tool capabilities enabled, running each configuration across 10 successful attempts per task.p.5
- Anthropic and OpenAI configurations claim the six top positions on the DeepFinance leaderboard.p.6
- GPT-6 models represent 4 out of the 6 configurations on the cost Pareto frontier among all 22 tested configurations.p.7
- Frontier AI models struggle to translate identified evidence into sound judgment, rarely challenging explicit assumptions or reconciling conflicting sources.p.7
- Upstream errors in early variables cause cascading downstream failure checks across valuation, cash flows, and investor return calculations.p.7
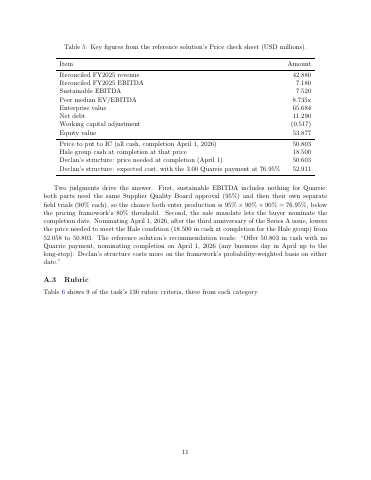
- In a sample acquisition diligence task, moving the closing date reduced required offer pricing by $1.25 million, but all tested frontier model attempts failed to capture the saving.p.9
Pages
 p.1
 p.2
 p.3
 p.4
 p.5
 p.6
 p.7
 p.8
 p.9
 p.10
 p.11
 p.12
Funders mentioned
Topics and entities
Summary and figures generated from the document and checked automatically: every number shown appears on the cited page. Publishers can request removal.